Lattice: AI Evaluation Methodology and Toolkit
A measurement framework for consistent, evidence-based human evaluation of AI-generated responses.
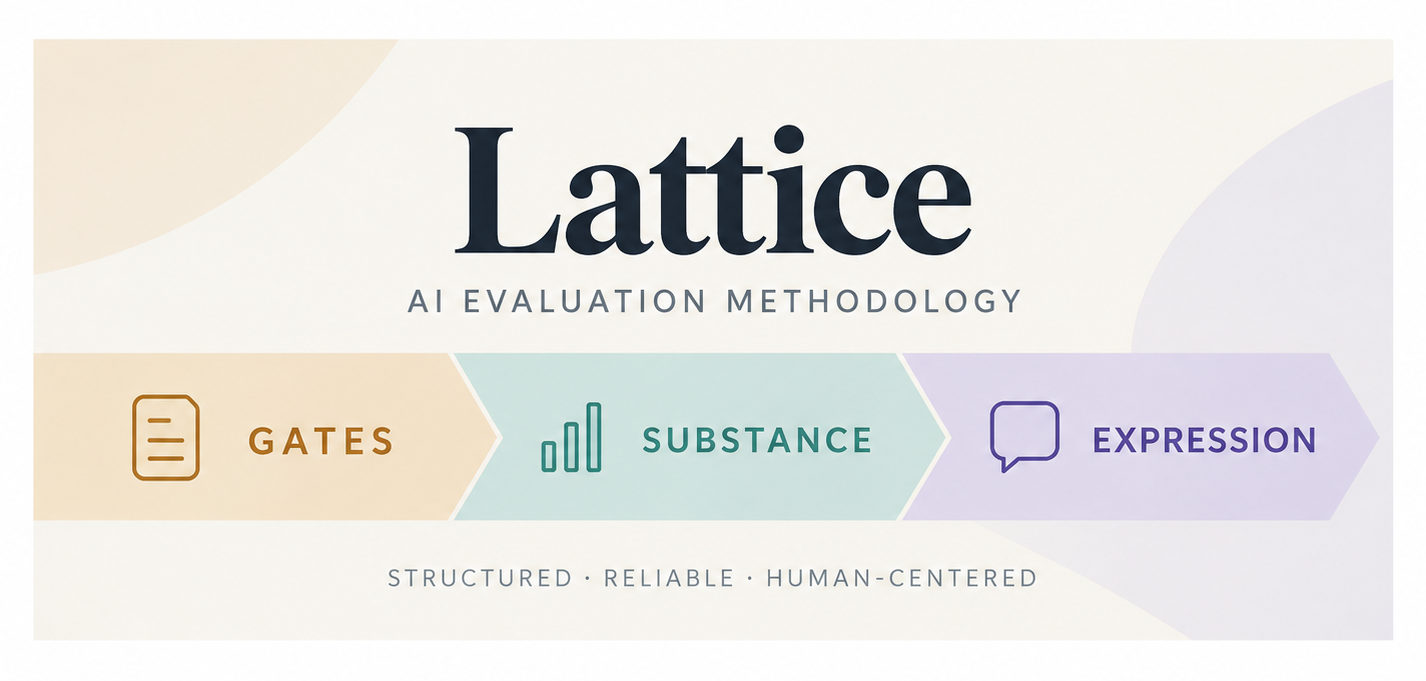
When different evaluators score the same AI response, they often disagree, not because they are careless, but because they are working from different mental models of quality. I developed a structured evaluation methodology grounded in construct validity, rubric design, and inter-rater reliability research, defining ten constructs across three evaluation tiers, building behavioral scoring rubrics, and designing decision rules that hold even in ambiguous cases. I then designed an interactive toolkit that puts the methodology to work in a guided evaluator workspace.
Prepdeck: AI Co-pilot for Educators
Education Co-Pilot is an AI-powered coaching prototype designed to help teachers and school leaders use AI more effectively in their everyday work. Rather than simply generating answers, it guides educators through identifying the right role for AI, choosing appropriate tools, building reusable workflows, and maintaining professional judgment. The goal is to solve real workplace challenges while building long-term AI fluency.
What I did: I worked with a partner during the early stages to develop and test the initial concept and conversation framework. I then took the project through later iterations independently—redesigning the interface, refining the interaction flow, developing the working prototype, and testing and documenting the experience across scenarios. The final design reflects my decisions about how the tool should guide users, when AI should (and should not) be involved, and how AI literacy should be built into the workflow.
Final prototype: View the design overview
Earlier iterations: See how the prototype evolved
Prompt Quality Evaluation — Interactive Walkthrough
While building Prepdeck (above), the user prompt the co‑pilot generated turned out to be the real product, and that raised a harder question: how do you actually tell whether a prompt is any good?
This project is my answer. It is a four‑phase system that turns that fuzzy question into something measurable, moving from a research‑backed framework, to two AI evaluators tested against each other, to a human evaluation step, to an effectiveness analyzer in progress.
Unlike the case studies above, this one is a live, interactive page you click through in your browser, not a PDF. You can toggle the evaluators, open each construct, and explore the tool itself. Built and hosted on GitHub.
Explore the interactive project here
 Homepage
